The Strategic Role of the Agent Harness in Enterprise Artificial Intelligence Deployment

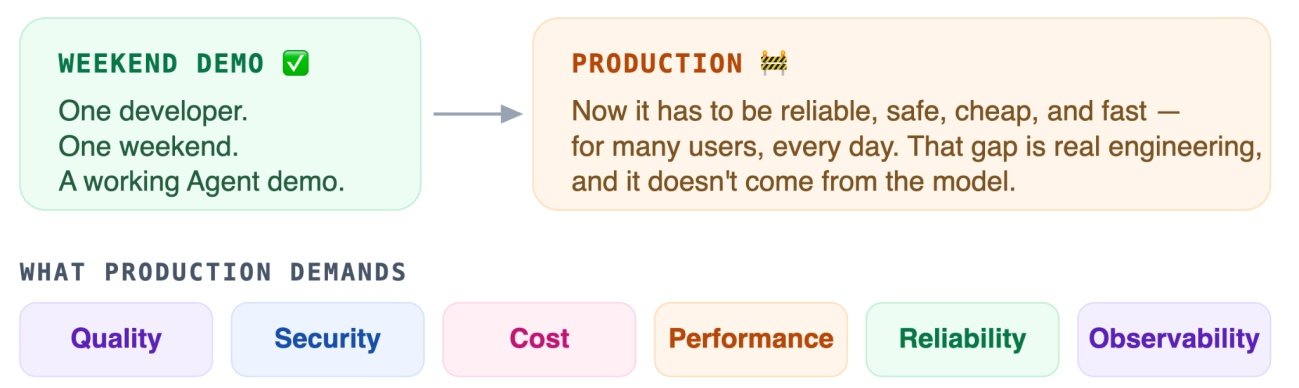
Transitioning an artificial intelligence agent from an afternoon demonstration project to a production-ready system is a chasm that separates many experimental prototypes from viable enterprise software. While foundational large language models (LLMs) provide the cognitive engine for these systems, the operational maturity of an agent is dictated by its "harness"—the architectural scaffolding that ensures safety, reliability, cost-efficiency, and observability.
As organizations move beyond the "hype" phase of generative AI, the focus has shifted toward building resilient systems. This shift mirrors the evolution of cloud-native development, where the infrastructure surrounding the application—the DevOps layer—often becomes more complex and critical than the application logic itself.
Defining the Agent Harness
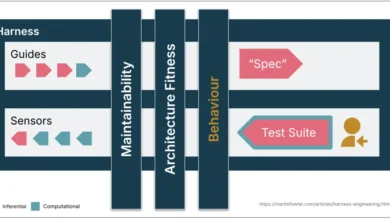
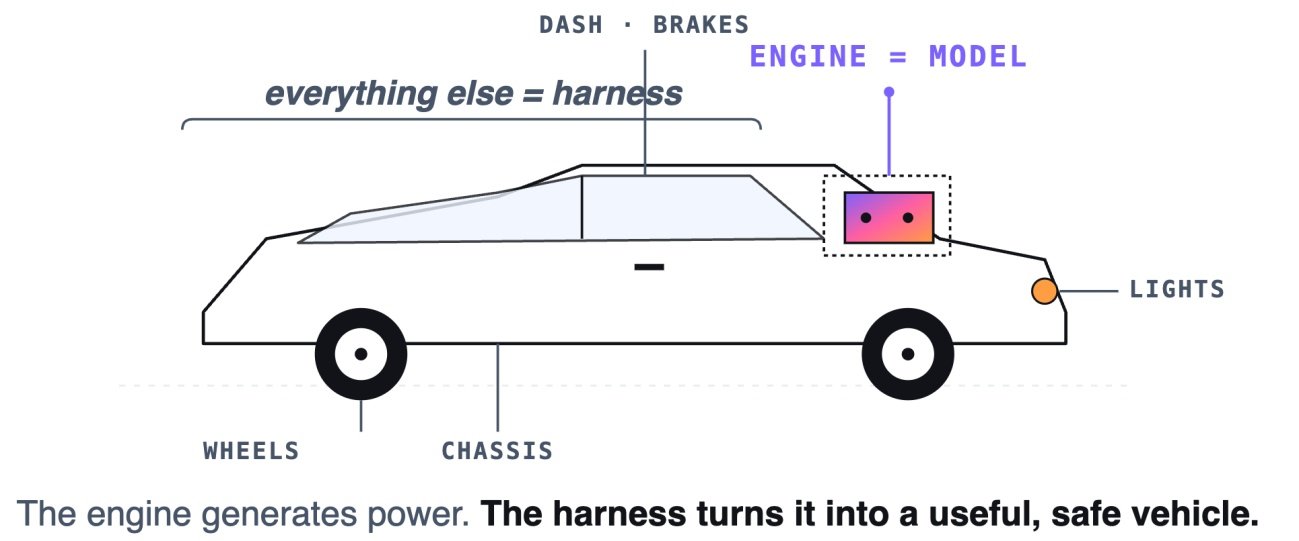
The concept of an "agent harness" has gained significant traction within the software engineering community over the past 12 months. As Vivek Trivedy of LangChain famously posited, an AI agent is effectively a model plus a harness. If the model is the engine, the harness is the chassis, braking system, and dashboard that makes the vehicle safe for public use.
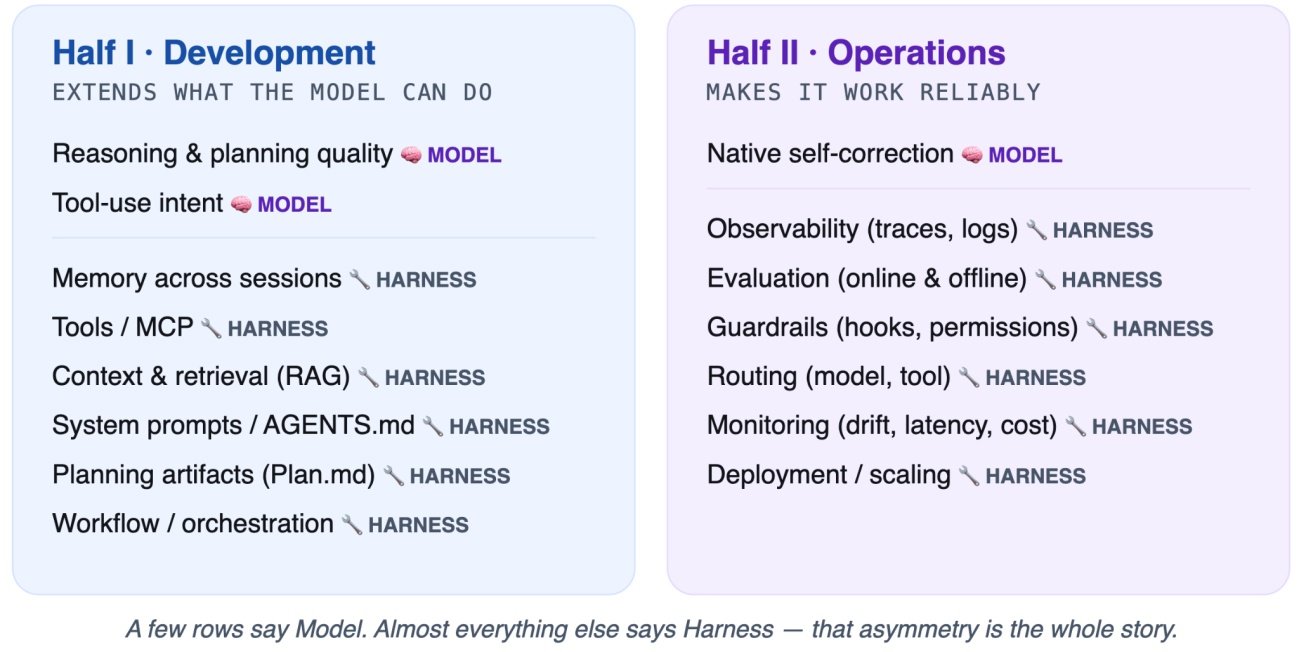
Historically, developers were forced to cobble together disparate scripts to handle retries, logging, tool integration, and prompt tuning. Today, the harness is being treated as a first-class engineering concern. It is split into two distinct operational domains: development and operations.
The development half focuses on extending the model’s capabilities: persistent memory across sessions, Model Context Protocol (MCP) integration for tool access, retrieval-augmented generation (RAG) pipelines, and complex prompt orchestration. The operations half, which shares significant DNA with traditional Site Reliability Engineering (SRE), covers observability, automated evaluation, guardrails, cost-capping, and deployment scaling.
Architectural Approaches: Managed vs. Self-Managed
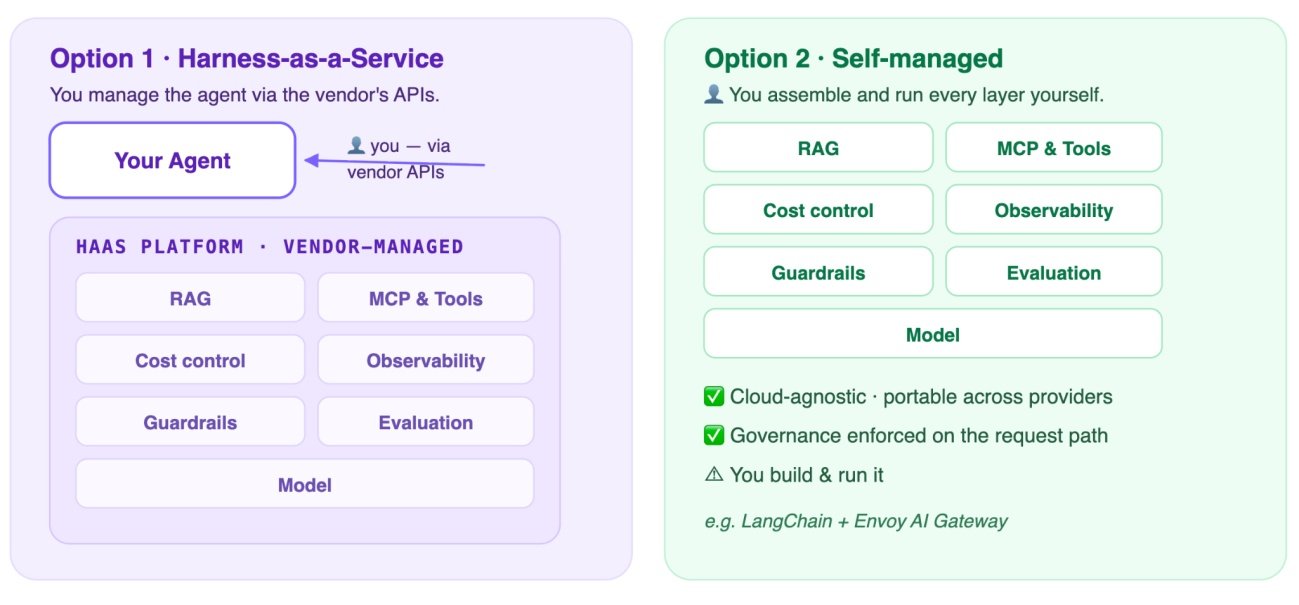
Organizations currently face a choice between two primary deployment strategies: Harness-as-a-Service (HaaS) and self-managed stacks.
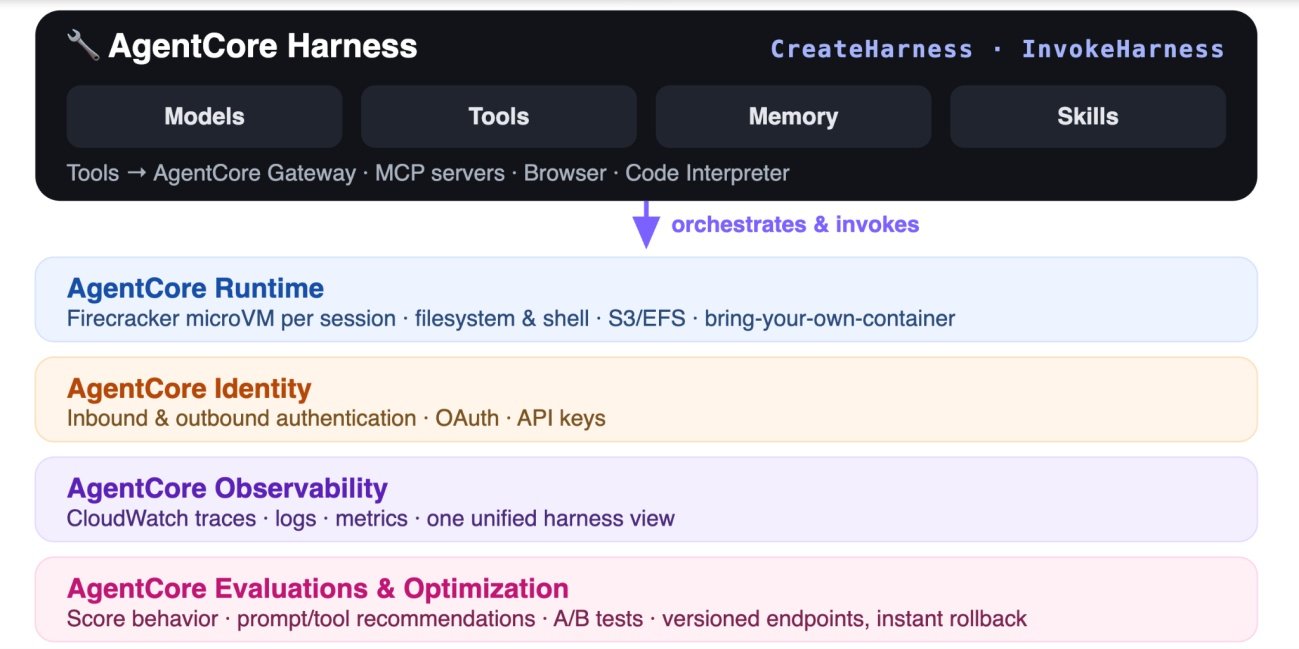
HaaS platforms, such as Amazon Bedrock AgentCore, Google Vertex AI Agent Engine, or the LangGraph Platform, provide a vendor-run runtime that encapsulates the harness behind managed APIs. These services are designed for speed, allowing teams to configure memory, identity, and observability through standardized configuration objects rather than manual code orchestration. In this model, the provider handles the underlying infrastructure, such as microVM isolation and telemetry collection.
Conversely, the self-managed approach relies on open-source components and SDKs. Teams often utilize frameworks like LangChain or LlamaIndex in conjunction with specialized gateways like Agent Router (formerly Envoy AI Gateway). This approach requires more upfront engineering investment—including the management of Kubernetes clusters, CI/CD pipelines, and on-call rotations—but offers superior control and cloud-agnostic portability.
Case Study: FinBot and the Mechanics of Production
To illustrate the difference, consider "FinBot," a hypothetical finance assistant tasked with summarizing quarterly revenue. The agent must pull filings from a document store, utilize a code interpreter for numerical analysis, and draft a coherent summary.
In a managed harness environment, the developer defines the agent’s behavior through a configuration schema. The runtime automatically manages the "firecracker" microVMs for session isolation, logs traces to CloudWatch, and handles memory expiration. The complexity is hidden; the developer specifies the toolset and the model, and the platform provides the operational wrapper.
In a self-managed environment, the architecture is explicit. The agent acts as a client to an AI gateway. This gateway, built on Envoy Proxy, performs token-based rate limiting, authenticates requests against backend models, and injects the necessary security credentials. Because this runs on the user’s own infrastructure—such as Amazon EKS or Google GKE—the organization retains full ownership of the data path and the specific versions of the software stack.
Operational Pillars: Cost, Observability, and Scaling
A critical factor in the failure of early AI projects is the lack of "guardrails." Without them, a recursive agent loop can lead to uncontrolled API calls and, subsequently, exorbitant utility bills.
Managed services mitigate this by enforcing hard caps on iteration counts and token usage at the infrastructure level. Self-managed teams must implement these controls via the gateway, typically by defining global rate-limiting policies that track token consumption across different user segments.
Observability remains the most significant hurdle for production-level agents. In a distributed environment, an agent is often a "black box" where prompts, tool calls, and responses are disjointed. Modern implementations leverage the OpenTelemetry (OTel) standard to unify these signals. By using a shared vocabulary for trace spans, such as gen_ai.client.token.usage, engineers can correlate latency and cost data across multiple model providers.
Whether an organization opts for HaaS or a self-managed stack, the instrumentation requirements are effectively the same. Developers must decide which data—such as specific message content within a prompt—is captured in logs and who maintains access to those sensitive traces.
Market Implications and Future Outlook
The shift toward standardized agent harnesses signals that the AI industry is entering a phase of industrialization. Just as the emergence of Linux and Kubernetes once standardized the deployment of web applications, the rise of the agent harness is creating a predictable pattern for AI agent deployment.
Market analysis suggests that while managed services will likely capture the majority of mid-market and rapid-prototyping use cases, large enterprises with strict compliance or multi-cloud requirements will continue to invest in self-managed stacks. The ability to switch model providers—or "canary" a new, more efficient model into production without rewriting the application code—is becoming a competitive necessity.
Furthermore, as multi-agent workflows (where specialized agents communicate with one another) become more common, the role of the harness will only grow in importance. Orchestrating these workflows requires a robust control plane that can manage the state, inter-agent communication, and security boundaries between multiple cognitive modules.
Conclusion
Building an AI agent is no longer about finding the most sophisticated model; it is about building the most reliable system around that model. The distinction between a demo and a production system is defined by the harness—the set of constraints, monitoring tools, and architectural choices that ensure the system operates within defined business parameters.
As the ecosystem matures, developers will increasingly rely on these standard frameworks to manage the complexities of LLM-based applications. Organizations that prioritize the development of a robust harness early in their AI roadmap are significantly better positioned to scale their capabilities and mitigate the operational risks inherent in deploying autonomous AI agents. The future of enterprise AI lies not in the model itself, but in the engineering excellence of the harness that supports it.