Fine-Tuning vs. Frozen Embeddings: When to Adapt the LLM vs. the Sklearn Head

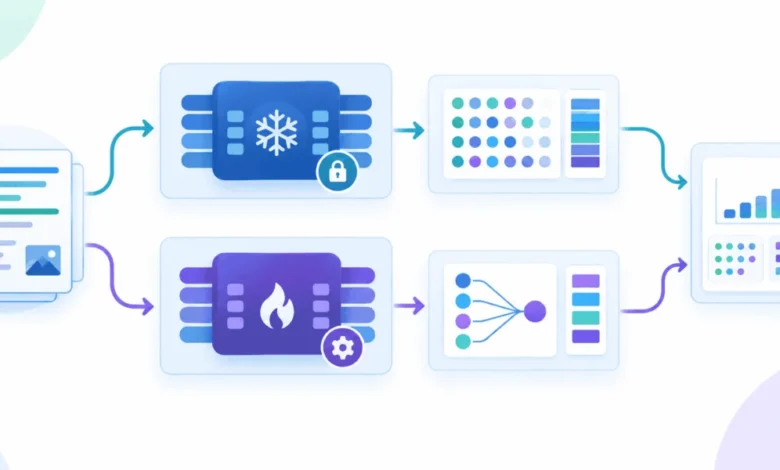
In the rapidly evolving landscape of machine learning, developers are frequently faced with a pivotal architectural decision: whether to fine-tune a Large Language Model (LLM) to meet domain-specific requirements or to utilize the model as a static feature extractor paired with a lightweight downstream classifier. As businesses look to integrate artificial intelligence into cost-sensitive, compute-constrained environments, the debate between parameter-efficient fine-tuning (PEFT) techniques like Low-Rank Adaptation (LoRA) and traditional Scikit-learn classification on frozen embeddings has moved to the forefront of engineering discussions.
The Evolution of Domain Adaptation
Historically, the machine learning community relied on heavy fine-tuning, where all weights of a neural network were updated during the training process. This was computationally expensive and often prone to "catastrophic forgetting," where the model loses its general knowledge while learning new domain-specific tasks. The introduction of transformer-based architectures and subsequently Large Language Models shifted the paradigm.
The current industry standard for efficiency is LoRA. Introduced in 2021, LoRA allows developers to freeze the pre-trained weights of an LLM and inject trainable rank-decomposition matrices into the model’s architecture. This method significantly reduces the number of parameters that require gradient updates, making it possible to adapt models with billions of parameters on consumer-grade hardware. However, this progress has not rendered simpler methods obsolete. The use of frozen embeddings—treating the LLM as an opaque vectorization engine—remains a robust alternative for classification tasks, offering a stark contrast in resource allocation and performance overhead.
Methodological Comparison: The Frozen Approach
Strategy A involves utilizing a pre-trained LLM strictly as a feature extractor. In this framework, the model remains entirely immutable; its internal weights are locked. When a text input is provided, the model processes the sequence and outputs high-dimensional hidden states. By performing "mean pooling" on the final hidden layer, engineers can generate a fixed-length vector that represents the semantic essence of the input.
This vector is then treated as an input feature for a traditional machine learning algorithm, such as a Random Forest classifier or a Logistic Regression model implemented via the Scikit-learn library. This approach is highly efficient because it isolates the intensive computational cost of the LLM to the inference phase, while the training phase—the actual learning of the classifier—takes place in seconds. From a project management perspective, this methodology is favored in environments where rapid prototyping is required or where the infrastructure budget prohibits the GPU-heavy training cycles associated with full fine-tuning.
Methodological Comparison: The LoRA Paradigm
Strategy B, or QLoRA (Quantized Low-Rank Adaptation), represents the cutting edge of memory-efficient model adaptation. By quantizing the base model to 4-bit precision, developers can drastically shrink the memory footprint required to hold the model in VRAM. During the fine-tuning process, the LoRA adapters learn to shift the model’s activations toward the desired distribution of the target dataset.
While this approach generally yields higher accuracy—often closing the performance gap left by static embeddings—it requires a significantly longer training time. During the fine-tuning process, the model must propagate gradients through the adapter layers for every epoch, a process that is inherently more demanding than training a standalone classifier. The trade-off is clear: one trades computational time and electricity for a marginal, yet often critical, increase in predictive precision.
Comparative Data and Empirical Observations
In a controlled experiment using the AG News dataset—a collection of over 120,000 news articles categorized into four classes—the differences between these two strategies become quantifiable. When limiting the training set to a sample of 800 examples for rapid iteration, the frozen embedding approach required approximately 96.5 seconds for feature extraction, followed by a negligible 2.8-second training period for the Scikit-learn Random Forest classifier. This resulted in an accuracy of 82%.
Conversely, the LoRA-based fine-tuning approach required 300.3 seconds to train over three epochs. While this process was three times longer than the Scikit-learn implementation, it yielded an accuracy of 87%. This five-percentage-point increase is the central metric for stakeholders: the value of the incremental accuracy must be weighed against the increased energy expenditure and time-to-market.
Technical Implications and Resource Management
The choice between these two methodologies is not merely a matter of accuracy; it is an exercise in resource management. Frozen embeddings are ideal for "cold start" scenarios where a project must be deployed with minimal latency in training. Furthermore, because the classifier is external to the LLM, it is easier to maintain and version-control. If the underlying data distribution changes, one can retrain the small Scikit-learn model without ever needing to touch the heavy LLM again.
LoRA, however, is superior for tasks that require the model to "understand" deep, idiosyncratic patterns within a specific industry. For example, in medical or legal document classification, where the nuance of language is highly specialized, the internal representations of the LLM may need to be actively adjusted. By using LoRA, the model itself begins to align with the domain’s syntax and semantics, providing a more coherent classification backbone than a static frozen model ever could.
Broader Impact on AI Deployment
The industry is currently witnessing a shift toward "inference-first" architectures. As companies move away from monolithic AI solutions toward modular, specialized agents, the demand for lightweight, high-performance classification will only increase. Organizations that master the distinction between these two methods will be better equipped to optimize their cloud spend.
For many generative applications, such as chatbots or content synthesizers, full or LoRA-based adaptation is non-negotiable, as the model must learn to generate specific outputs rather than merely classify them. However, for the vast majority of enterprise use cases—such as sentiment analysis, ticket routing, or spam filtering—the "frozen" strategy provides a surprisingly high baseline of performance with a fraction of the operational risk.
Strategic Recommendations for Practitioners
When determining which strategy to employ, engineers should consider the following criteria:
- Dataset Size: If the dataset is small and the labels are distinct, frozen embeddings are often sufficient. If the dataset is massive and the patterns are complex, LoRA is likely necessary to capture the signal.
- Compute Budget: In environments where GPU time is expensive or limited (such as shared research clusters or cost-capped cloud instances), the 3x time difference seen in our testing indicates that frozen embeddings offer a better return on investment.
- Accuracy Sensitivity: If the application has a low tolerance for error—such as regulatory compliance or automated safety filtering—the performance gains provided by fine-tuning (the 5% gap noted in the test) may justify the increased compute costs.
- Model Stability: Frozen embeddings are inherently more stable. Because the LLM backbone is never modified, there is no risk of the model developing "drift" or degraded reasoning capabilities over time.
Future Outlook
As hardware capabilities grow, the delta between these two methods may shrink. The introduction of 1-bit quantization and increasingly efficient hardware-level optimization will make fine-tuning even faster. Yet, the architectural split between "feature extraction" and "parameter adaptation" will remain a fundamental concept in machine learning engineering.
Ultimately, the most successful implementations of LLMs in the coming decade will not be those that throw the most compute at a problem, but those that choose the most efficient path to reach the desired level of accuracy. Whether through the surgical precision of LoRA or the elegant simplicity of a Scikit-learn head on frozen embeddings, the objective remains the same: transforming raw data into actionable intelligence with minimal waste.