A Gentle Introduction to Model Distillation and the Escalating Industry Conflict

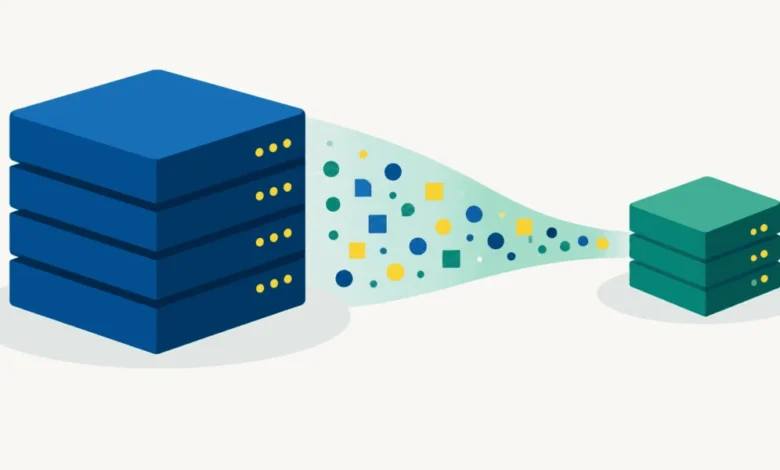
The global artificial intelligence sector is currently navigating a fundamental tension between the democratization of high-performance models and the protection of proprietary intellectual property. At the heart of this struggle is model distillation, a sophisticated machine-learning technique that allows developers to transfer the capabilities of massive, computationally expensive "teacher" models into leaner, more efficient "student" models. While distillation has long been considered a cornerstone of efficient software engineering, its recent application—specifically the unauthorized, large-scale extraction of intelligence from industry-leading systems—has triggered a series of high-stakes allegations, regulatory scrutiny, and a profound rethinking of how AI models are deployed and secured.
The Mechanism of Intelligence Transfer
At its core, model distillation addresses a critical scalability bottleneck. Modern foundation models, such as GPT-4, Claude, and Gemini, represent the pinnacle of AI capability, yet they possess hundreds of billions of parameters. Running these systems requires massive data centers, significant energy consumption, and high latency, making them ill-suited for edge computing or mobile applications.
Distillation solves this by leveraging "dark knowledge." In traditional supervised learning, a model is trained on "hard labels"—binary, ground-truth data points. However, a teacher model provides a richer signal by outputting a probability distribution. For instance, if an image classification model analyzes a photo of a golden retriever, it does not merely categorize it as a "dog"; it may output a 90% probability for dog, 8% for wolf, and 2% for cat. These subtle relational insights, known as "soft targets," allow a student model to learn the nuances of the teacher’s reasoning, enabling the student to perform at a level far beyond what its smaller parameter count would typically allow.
The Evolution of Modern Distillation Techniques
The framework for distillation was popularized in 2015 by Geoffrey Hinton, Oriol Vinyals, and Jeff Dean. While their initial work focused on image classification and speech recognition, the rise of large language models (LLMs) necessitated a shift in methodology. Because LLMs generate text token by token across massive vocabularies, classical logit-based distillation—which requires access to the teacher’s internal probability outputs—has become less prevalent than modern alternatives.
Today, three primary methods dominate the landscape:
- Synthetic Data Distillation: This has emerged as the industry standard. A teacher model is prompted to generate vast amounts of high-quality reasoning chains, code, and structured text. A smaller student model is then fine-tuned on this synthetic output. This method is highly effective because it requires only API access, not internal architectural secrets.
- Feature Distillation: This involves training the student to mimic the activation patterns of the teacher’s intermediate layers. This creates a deeper structural alignment but necessitates full access to the teacher’s neural weights.
- Logit-Based Distillation: This remains the most direct application of Hinton’s original framework, matching the full token probability distributions at each step. It is typically reserved for internal R&D where the organization maintains control over the entire pipeline.
Chronology of the Unauthorized Distillation Crisis
The transition of distillation from a standard engineering practice to a flashpoint for international conflict began to accelerate in early 2026. As smaller, open-weight models began to rival proprietary systems in performance, major AI labs became increasingly concerned that their public-facing APIs were being used as "data mines" to train competing models.
- April 2026: During a legal deposition, Elon Musk confirmed that xAI had utilized OpenAI’s models during the training phase of Grok. Musk characterized this as an industry-standard practice, highlighting that the line between legitimate distillation and competitive "harvesting" is often porous.
- May 2026: OpenAI submitted a formal memo to the U.S. House Select Committee on China, alleging that DeepSeek had systematically circumvented API protections to extract proprietary intelligence.
- June 2026: Anthropic released findings alleging that approximately 24,000 accounts were linked to a massive campaign targeting the Claude API. The company reported that over 16 million exchanges were used to probe and distill the model’s agentic reasoning and coding capabilities.
- June 2026 (Mid-month): Anthropic further alleged that Alibaba’s Qwen lab was responsible for a campaign involving 28.8 million exchanges over 44 days. Alibaba publicly denied these allegations, marking a significant escalation in the diplomatic and corporate tension surrounding AI development.
Economic and Strategic Implications
The economic stakes of these allegations are immense. A primary concern is the "cost-shifting" of research and development. If a laboratory invests over $1 billion to train a frontier model, and a competitor can distill a significant portion of that intelligence for a fraction of the cost—often by using the target lab’s own infrastructure—the fundamental business model of AI labs is undermined.
Data from industry analysts at SemiAnalysis suggest that while some labs report training costs in the low millions, these figures often ignore the cumulative R&D and infrastructure investment required to achieve those results. By "harvesting" the output of a frontier model, an entity can potentially leapfrog years of foundational research.
Official Responses and Industry Defenses
In response to the surge in unauthorized harvesting, major labs have begun to harden their infrastructure. The current defensive landscape includes:
- Anomaly Detection: Monitoring API traffic for patterns consistent with automated, high-volume "probing" rather than human usage.
- Output Watermarking: Embedding subtle signals in text generation that allow labs to identify if a piece of text was generated by their model.
- Rate Limiting and Tiered Access: Tightening the parameters of how many tokens a single user can generate, which impacts both malicious actors and legitimate power users.
- Coalition Building: OpenAI, Anthropic, and Google have reportedly begun sharing intelligence on distillation patterns, signaling an unprecedented level of inter-company cooperation to protect their proprietary assets.
The Legal and Regulatory Quagmire
Despite the intensity of the conflict, the legal path forward remains murky. Under current U.S. copyright law, the outputs of an AI model are not inherently protected in the same way as human-authored works. Furthermore, the technical methods used to "obfuscate" distillation requests—such as using third-party routing services to mask the origin of a prompt—make enforcement difficult, particularly across international jurisdictions.
The debate is ultimately about whether "distillation" constitutes a form of intellectual property theft or merely the natural evolution of open-source competition. While companies like Meta have actively encouraged the distillation of their Llama 3.1 models, arguing that it promotes ecosystem growth, labs like OpenAI and Anthropic argue that the non-consensual extraction of capabilities from closed models is a direct threat to the safety and viability of the industry.
Conclusion: A Structural Paradox
The tension between the accessibility of AI and the protection of technological advancement is unlikely to reach a simple resolution. Distillation is a dual-use technology: it is both an essential tool for scaling AI to the masses and a powerful weapon for competitive extraction. As the industry moves forward, the focus will likely shift from purely performance-based metrics to "defensible intelligence"—building models that are not only capable but also architecturally resistant to the very techniques that have defined the last decade of machine learning progress. For now, the practice of model distillation remains a critical, yet deeply contested, frontier in the development of artificial intelligence.